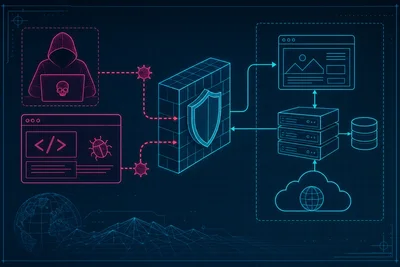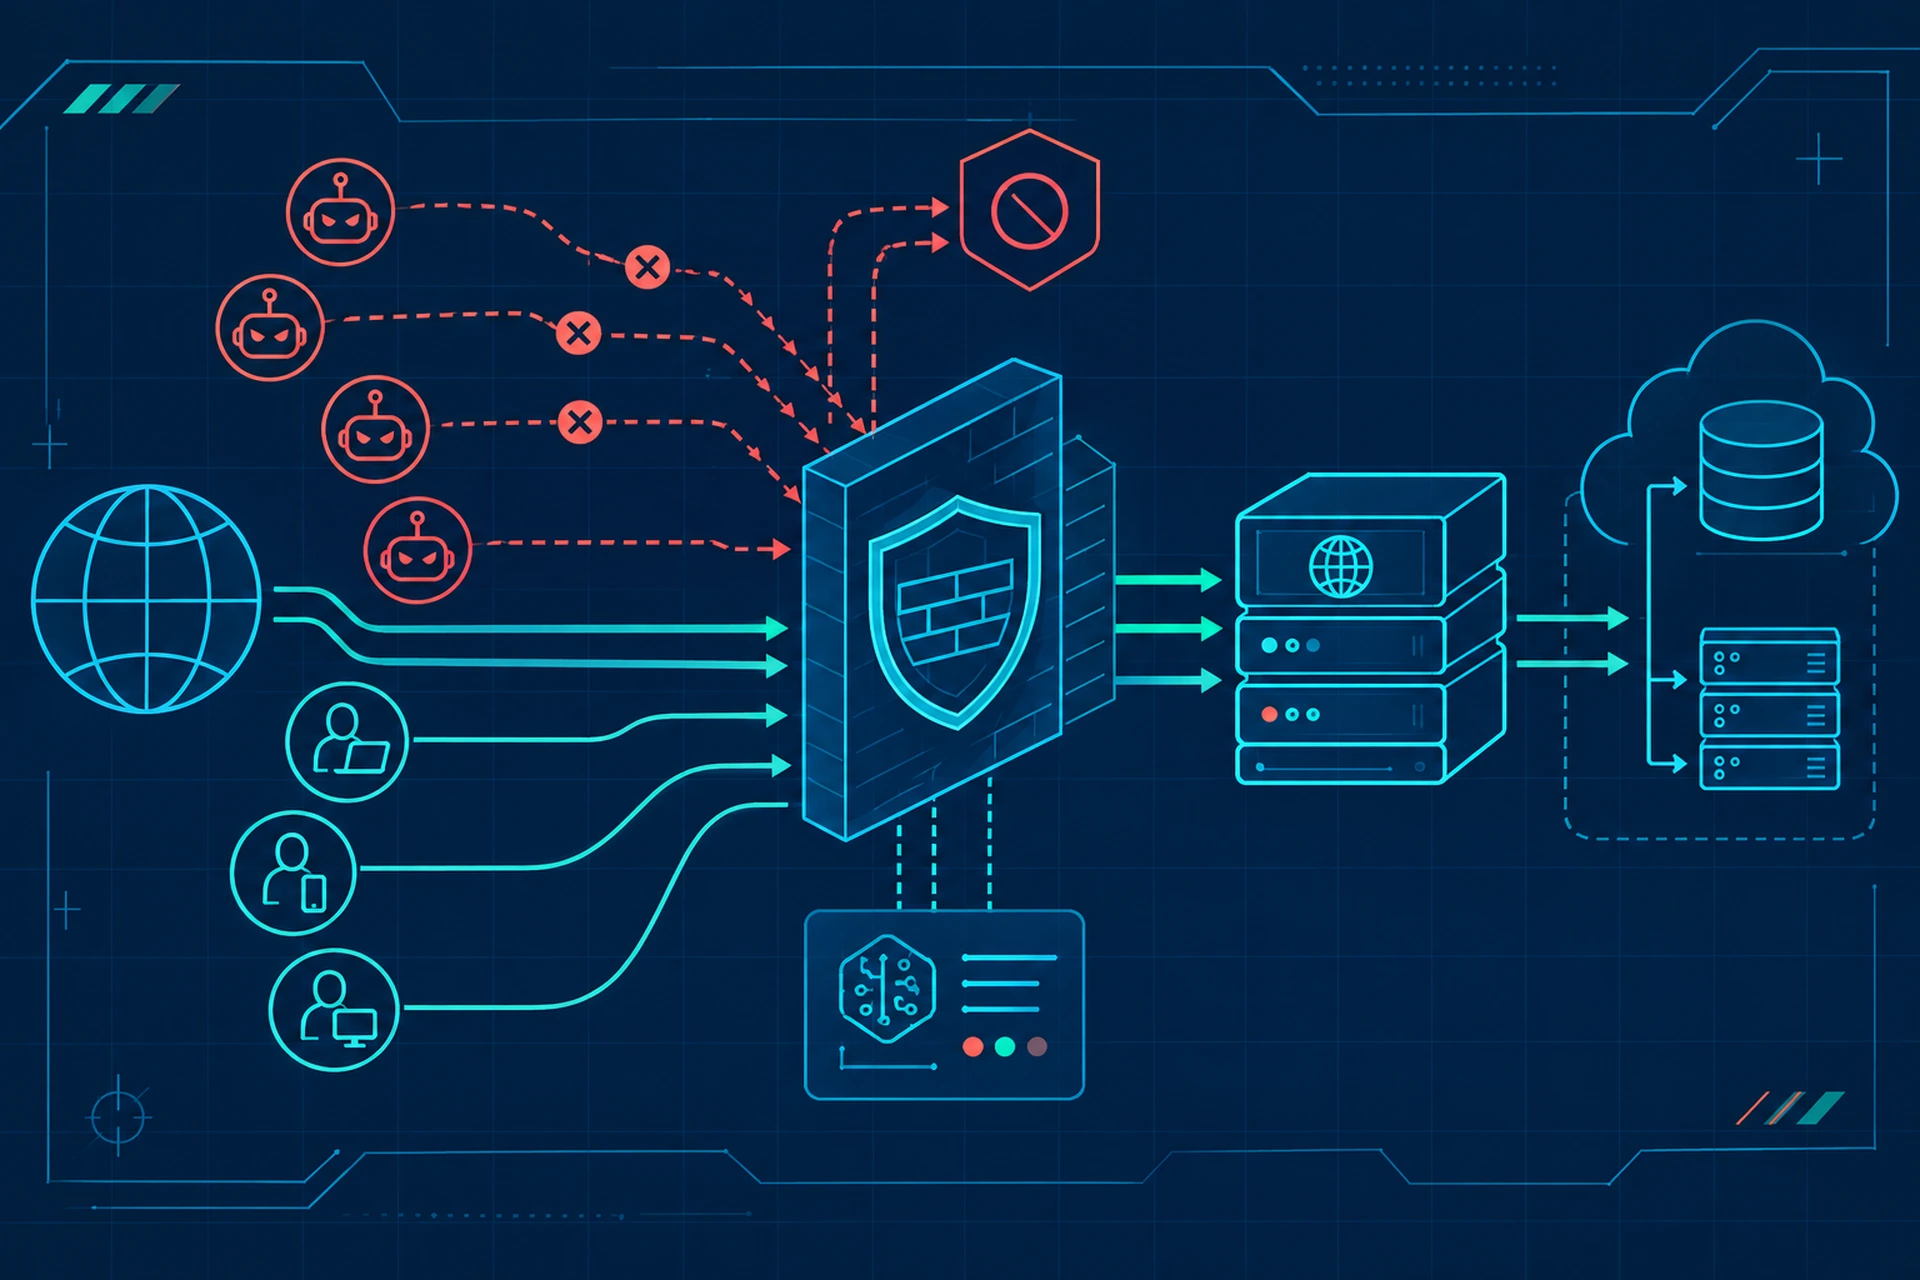
Bots make up more than half of all internet traffic today. Some of that traffic is helpful, like search engine crawlers indexing your pages. A lot of it isn't. Scrapers steal your content, credential-stuffing bots try stolen passwords against your login page, and inventory bots snipe your checkout before real customers get a chance. The tricky part isn't just spotting bad bots. It's telling them apart from real people without accidentally locking out your paying customers.
This is exactly the balancing act a web application firewall is built for. Let's look at how it actually pulls this off.
Why Bot Traffic Is Harder to Filter Than It Sounds
Blocking a bot sounds simple until you try it. A bot can use the same browser headers as a human. It can rotate through thousands of IP addresses. It can even solve basic CAPTCHAs with automated services. Meanwhile, your real visitors might be using VPNs, corporate proxies, or unusual browser extensions that make them look a little suspicious too.
A web application firewall has to sort through all of this noise in real time, on every single request, without adding noticeable delay. That's a much harder problem than just checking an IP against a blocklist.
How a Web Application Firewall Actually Tells Bots From People
Behavioral Patterns, Not Just Signatures
Traditional firewalls rely heavily on known signatures, like a specific user agent string or a flagged IP range. Modern web application firewall rules go further by watching behavior. Real humans click around, pause to read, move their mouse, and take a few seconds between page loads. Bots tend to move in straight lines. They hit pages at inhuman speed, skip resources a browser would normally load like images or CSS, and repeat identical request patterns over and over.
When a WAF sees a client requesting fifty product pages a second with no time spent scrolling or reading, that's a strong behavioral signal, even if every header looks legitimate.
Rate Limiting With Context
Simple rate limiting alone would punish real users during a busy sale or a viral traffic spike. A smarter approach applies limits per endpoint and per context. A login page might allow five attempts a minute per IP, while a product listing page allows far more, because browsing behavior looks different from credential testing behavior. This kind of contextual rate limiting is a core part of how a web application firewall keeps bad actors out while letting legitimate spikes through. We covered the mechanics of this in How Rate Limiting and Traffic Scrubbing Work Together in DDoS Protection Hosting.
Fingerprinting Beyond the IP Address
IP addresses alone are a weak signal these days. Residential proxy networks let bot operators route traffic through thousands of real home IP addresses, making the traffic look geographically distributed and legitimate. A capable WAF looks deeper: TLS fingerprints, JavaScript execution checks, header ordering, and consistency between claimed browser and actual behavior. If a request claims to be Chrome on a phone but the TLS handshake matches a known scraping library, that mismatch gets flagged.
Challenge-Response Without the Friction
When a WAF isn't fully sure, it doesn't have to choose between blocking outright or letting the request through blind. It can issue a lightweight challenge, like a JavaScript computation that a real browser solves instantly but a basic bot script can't. This happens invisibly to the visitor most of the time. Only when the traffic is genuinely ambiguous does a user see something like a short verification step, and even then it should take a few seconds, not minutes.
Good Bots Still Need a Way In
Not every automated visitor is a threat. Search engine crawlers, uptime monitors, and payment gateway webhooks are all bots too, and blocking them breaks your SEO or your checkout flow. A properly tuned web application firewall maintains allowlists for known good bots verified by reverse DNS lookups, not just a user agent string that anyone can fake. This is one of the reasons a self-managed WAF configuration is riskier than it looks. Miss one legitimate crawler and your search rankings quietly suffer for weeks before anyone notices. We go deeper on this tradeoff in Managed vs. Self-Configured Web Application Firewall.
Where False Positives Come From (And How to Avoid Them)
Even well-tuned rules occasionally flag real people. Common culprits include:
- Corporate networks where hundreds of employees share one outbound IP address, tripping rate limits meant for individual bots
- Browser extensions or privacy tools that strip headers a WAF expects to see
- Aggressive ad blockers that alter request patterns in ways that resemble scraping
- Old mobile browsers with outdated TLS libraries that look similar to bot frameworks
Good WAF management means reviewing block logs regularly and adjusting rules instead of setting them once and forgetting about them. We walked through this process in detail in False Positives in a Web Application Firewall and How to Tune Them Without Breaking Your Site.
What This Means for Your Server Setup
If you're running your own WAF rules on a self-managed server, this kind of tuning takes ongoing attention. You need visibility into which requests are getting challenged or blocked, and the ability to adjust quickly when something breaks for real users. On a managed setup, this is handled for you, and the server's security section typically gives you visibility into bot IP lists and firewall rules without needing to touch a config file directly. That combination of automated filtering and easy oversight is what keeps bot traffic out without turning your checkout page into an obstacle course for real customers.
For a broader look at how this fits into the rest of your defenses, see our WAF overview and DDoS protection details.
The Takeaway
Handling bot traffic well isn't about blocking as much as possible. It's about telling the difference between a threat and a customer, in milliseconds, without either one noticing the process. Behavioral analysis, contextual rate limits, deeper fingerprinting, and lightweight challenges all work together to make that possible. If your current setup only checks IPs and user agents, it's probably letting sophisticated bots through while occasionally blocking legitimate visitors, and that's worth fixing sooner rather than later.